THE LINUX FOUNDATION PROJECTS
Category

Featured

Surviving the AI Slopageddon: Is Open Source Breaking?

By Featured, News

The Problem: From “Bricks” to “Concrete Walls”

Traditionally, Open Source was built like a brick house: humans shared small patches of code, talked to each other, and built a community.

Today, we are facing the “Concrete Wall Drop.” AI can generate entire modules in seconds. Instead of humans collaborating, we have AI agents “dropping” massive amounts of code into projects. This is what experts call AI Slop—code that looks professional and has great documentation, but is often messy, redundant, or plain wrong inside.

The Reviewer’s Nightmare

The biggest issue is that writing code is now infinite, but checking it is not. * The Bottleneck: AI can create 1,000 lines of code instantly, but a human still needs hours to make sure it doesn’t have security holes.

  • The Shift: The hard work has moved from the writer to the reviewer. Maintainers are getting exhausted trying to spot “hallucinations” hidden behind neat-looking AI formatting.

Why the System is Shaking

Open Source used to work because of visibility. You used a tool, talked to the creator, and maybe donated or hired them.

Now, AI agents act as middlemen. A user asks an AI for an app, the AI grabs the code, and the user never even sees the human who actually maintains it. This makes the developer’s work invisible. If the people building the foundations of our software aren’t seen or supported, they might just stop building.

What’s Next?

We are moving into an “AI-native” world. To survive the Slopageddon, the community needs to find new ways to:

  1. Spot the “Slop”: Filter out low-quality AI code automatically.

  2. Protect Humans: Make sure the people behind the code are still visible and supported.

  3. Redefine Trust: We can’t trust code just because it “looks” right anymore.

The bottom line: AI can write code, but it can’t take responsibility for it. Keeping humans in the loop is the only way to save Open Source.


Stream Introduction and FOSS license scanning: The why, the how and the community approach

By Featured

FOSSology: Open Source License Compliance

A recent presentation introduced FOSSology, a key tool for managing open source license compliance. The session covered its core functions, workflow, license identification, copyright handling, and reporting capabilities.

What is FOSSology?

FOSSology is a powerful, open-source (GPL-2.0 licensed) framework for managing open source compliance. It helps with:

  • License Management: Creating, modifying, and assigning risk levels and compatibility rules to licenses.
  • Obligation Management: Defining and linking obligations to licenses.
  • Acknowledgment Storage: Storing necessary acknowledgments.

While powerful, efficient use often requires training. Installation on Linux from source is straightforward. A key takeaway is that full license analysis cannot be entirely automated today.

FOSSology uses various agents for license identification (Nomos, Monk, Ojo, Scancode) and copyright processing (FOSSology agent, Scancode). It also includes agents for keyword search, IP, and ECC.

Overall Workflow

The typical FOSSology workflow involves:

  1. Creating a folder (if needed).
  2. Uploading the component (reusing phrases is possible).
  3. Running license analysis.
  4. Processing copyrights.
  5. Performing ECC checks.
  6. Editing and configuring settings.
  7. Downloading and reviewing reports.

Candidates and obligations can be added during license analysis. When uploading, users can ignore pre-configured folders (e.g., “tests,” “.github,” “examples”) to streamline the analysis. Options exist for automatic license conclusions, reusing data from past packages, and deactivating copyrights.

License Identification

Identifying the correct license is critical. FOSSology offers:

  • Multiple Scanners: Nomos, Monk, Ojo, Scancode.
  • Text Highlighting: For quickly spotting changes in license text.
  • Matched License Overview: Provides immediate insights without a full package analysis.

Differences between scanner findings and final conclusions are common. The tool supports manual file-by-file inspection, bulk identification via reports, and folder-level license assignment. It also handles individual license texts, acknowledgments, and comments.

For unknown licenses, manual searching might be needed. FOSSology allows adding comments to document the steps taken for a license conclusion, providing an audit trail in reports and SPDX tags. It supports Unicode in license texts.

License Compatibility: FOSSology allows defining custom compatibility rules or importing existing sets (e.g., from OSADL).

Copyright Statements

FOSSology extracts copyright statements using regular expressions. These often require post-processing to remove clutter, with two views available: file view and folder/upload view.

Reporting

FOSSology offers extensive reporting features at both component and folder levels.

Component Level Reports: DEPS files, ReadMe_OSS, SPDX V2/V3, CycloneDX, Unified Report, License List, Copyright List.

Folder Level Reports: ReadMe_OSS, SPDX V2/V3, CycloneDX.

A notable feature is “enable OSSElot export,” which generates valid SPDX files and well-formatted ReadMe_OSS, addressing the issue where SPDX specifications do not include full license texts in valid SPDX files, thus avoiding compliance pitfalls.

SPDX files generated by FOSSology adhere to SPDX-2.3, including checksums, license conclusions, comments, copyright info, and scanner findings.

OSSelot and FOSSology: Streamlining Open Source Compliance

A recent presentation highlighted OSSelot, an Open Source Curation Database, and its integration with FOSSology to simplify open source license compliance. The core message was that while some manual review remains essential, reusing curated licensing and copyright information can drastically cut the time needed to clear software packages.

What is OSSelot?

OSSelot is a public database offering curated compliance data for commonly used FOSS components and associated tools. It stores:

  • License and Copyright Analysis: Results from thorough analysis.
  • Metadata: Information like download location, package creators, reviews, and comments (often in README or info.json).
  • Standard Reports: SPDX (Tag:Value, JSON, YAML, RDF) reports with concluded licenses and copyright notices.
  • Disclosure Documents: Aggregated license texts, copyright notices, and acknowledgments per package.

How to use OSSelot Data with FOSSology

OSSelot data significantly streamlines compliance by allowing users to leverage pre-analyzed information. This can be done in two main ways:

1. Manual Workflow (via GUI):

  • Find closest version: Locate the nearest version of the package in OSSelot.
  • Upload and Reuse: Upload its source code to FOSSology without scanning, but use the “Reuse” function, referencing the OSSelot package. This automatically clears the package.
  • Upload required version: Upload the actual required version of the package. Run scanners, and then reuse the results from the previously cleared OSSelot package.
  • Manual clear: Manually clear any remaining (new or modified) files.

2. Automated Workflow (via FOSSology REST API):

This method offers greater automation, especially for large-scale operations.

  • Discover OSSelot versions: Use the REST API to find available OSSelot package versions.
  • Upload OSSelot source: Upload the source code of the relevant OSSelot package into FOSSology (e.g., using a curl command with the package URL). Crucially, this is done without scanning.
  • Trigger OSSelot Import: This step automatically clears the entire package within FOSSology based on the OSSelot data.
  • Upload required source: Upload the source code of the actual version you need to clear. Run scanners and reuse the data from the now-cleared OSSelot package.
  • Manual clear: Handle only the remaining (new or modified) files manually.

Key Benefits

The integration of OSSelot with FOSSology allows for:

  • Significant Time Savings: Reusing curated data drastically reduces the manual effort required for clearing packages.
  • Increased Accuracy: Leveraging expert-curated data improves the reliability of compliance conclusions.
  • Scalability: The API-driven approach enables automation for managing compliance across many components.

This synergy between OSSelot’s curated data and FOSSology’s powerful analysis capabilities presents a highly efficient solution for modern open source license compliance challenges.


Beyond the Code: Fostering Connection and Collaboration at the Women in Open Source Networking Event

By Featured

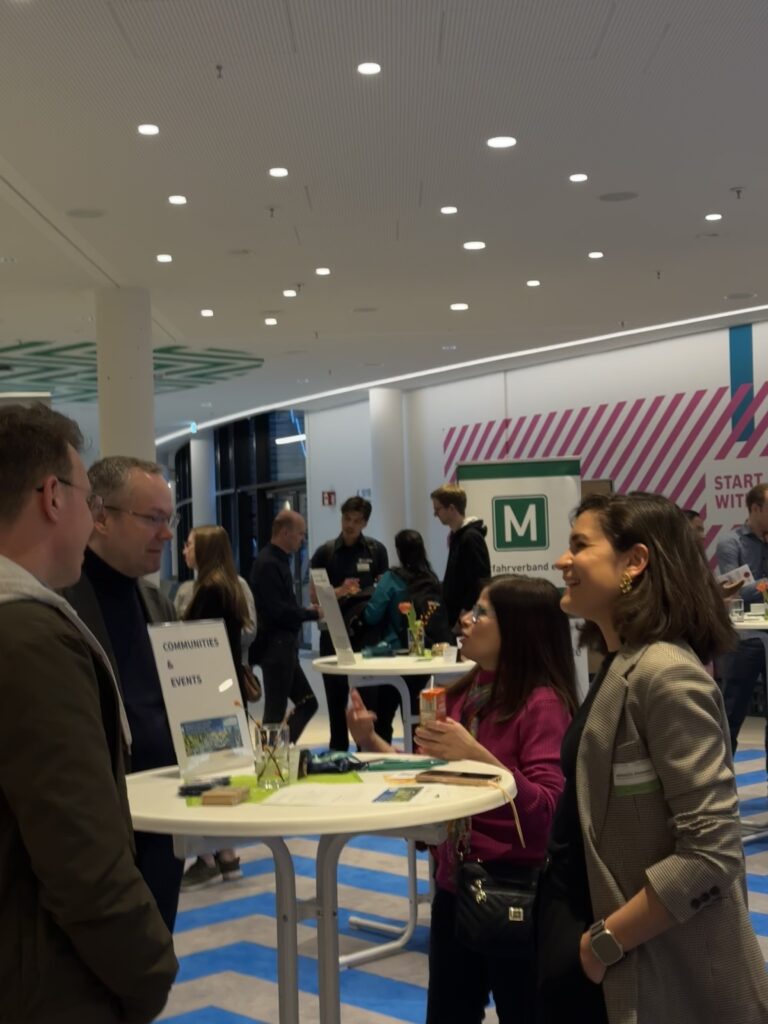
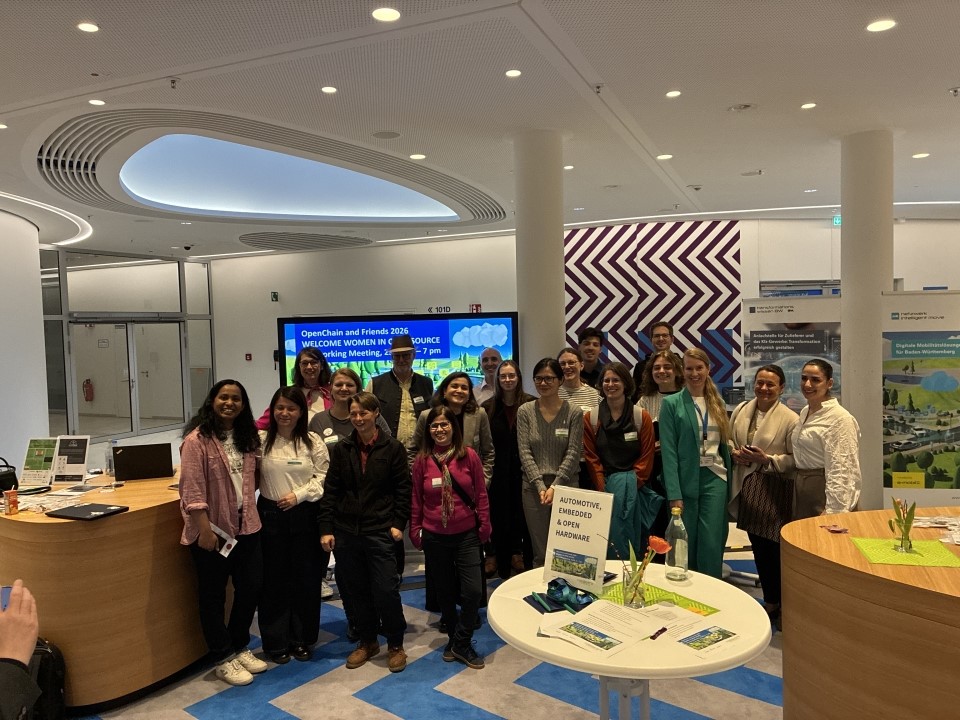
The energetic world of open source based not just on code, but on community, collaboration, and diverse perspectives. This was proved at a recent networking session designed specifically for women and allies in the open source ecosystem – an event that left attendees not only informed but deeply inspired. The session was organized as an open, moderated networking space, welcoming everyone who works with, contributes to, or is simply curious about Open Source. Its mission was to create environment for meaningful exchange, bridging technical, legal, business, and community perspectives.
Stepping into the event, I was experienced awesome energy in the place. It wasn’t just women interested in participating; it was a really diverse and welcoming group of people, and everyone seemed eager to chat even before the officially event started. People were already getting to know each other, swapping ideas, and just genuinely connecting. The format of the event encouraged dynamic interaction: two 30-minute discussion rounds were offered to the attendees. They had the freedom to choose themed tables that resonated most with their interests but aligned with broader topics of the Open Chain and Friends event. Participants could explore fresh perspectives, learn from each other, and build connections designed to last well beyond the evening. The diverse range of discussion themes included Communities, Compliance, Artificial Intelligence, Digital Sovereignty, Cybersecurity, Embedded and Open Hardware, Education and many others. Attendees quickly immersed themselves in discussions, sharing experiences and insights which led to dynamic and naturally flowing conversations.
It was fantastic to see so many different companies represented. This really helped us get diverse points of view and think about how we can all work together. The atmosphere was simply vibrant. By the end, the feedback was overwhelmingly positive. The enthusiasm was so high that discussions quickly turned to planning the next opportunity to meet, underscoring the success of building truly meaningful connections.

This event was a powerful reminder that while technology evolves rapidly, the human element – the desire to connect, learn, and collaborate – remains at the heart of the open source movement. A huge shout-out and thank you to the organizers and moderators – Adamantia Goulandris, Sarah Itt and Kurzmann Marcel – and special thank you for Women at Bosch for sponsoring this fantastic event!

KeyNote: The role of cybersecurity in supply chain and AI

By Featured

The cybersecurity topic stream at the first day of Open Chain and Friends event began with an impactful keynote from Dirk Targoni, spotlighting the critical connection between cybersecurity and open source. His practical session provided invaluable insights into navigating supply chain risks, emphasizing that effective remediation requires a holistic approach, not isolated solutions.

We gained clarity on essential factors: Asset Management (SBoM), Vulnerability Monitoring, Code and Binaries Checks, Pentesting, and robust Vulnerability and Incident Handling. A key takeaway was the interdependence of these elements – none are sufficient without the others. The session powerfully underscored that supply chain security has moved from the server room to the boardroom, driven by incidents where a single compromised dependency cascades rapidly.

Targoni also addressed the pervasive question, “Will AI take my job?” His reassuring answer: “AI is your assistant, can do the routine work for you”.

Secure AI Systems: Regulations, threats, defense mechanisms

By Featured

Following the foundational discussion on supply chain security, the cybersecurity session at Open Chain and Friends shifted focus to another rapidly evolving frontier: the critical importance of secure AI systems. Dr. Maike Massierer from Bosch took the stage, providing an insightful look into the topic. Her session highlighted the critical intersection of AI, cybersecurity, and regulation, especially within the automotive industry.

With AI increasingly powering automotive functions like road sign recognition and navigation, ensuring its security is paramount. Dr. Massierer demystified the EU AI Act, outlining its purpose: to ensure the safe and ethical use of AI across the European Union. Attendees learned about the serious implications of non-compliance and the vital importance of Article 15, which mandates AI systems to meet high standards of accuracy, robustness, and cybersecurity. Beyond regulation, the session offered practical insights into securing AI, with AI-specific Threat and Risk Analysis highlighting how crucial it is for addressing security needs effectively.

The Primacy of Trust

By Featured

The OpenChain and Friends event took place between 24 and 26 March 2026, with various tracks spread over three different locations, all focusing on the challenges we face in the supply chain. I’m not very good at writing about details—nor am I sure I’m even allowed to, since if I do that, it wouldn’t be hard to figure out who was the source of the information, and the conference did take place under the Chatham House Rule—but I’m fairly confident in my abilities to synthesize. And one thing that stood out to me is that, regardless of whether we’re talking about infrastructure, software, data, or AI agents, what we’re dealing with is really one big supply chain with various facets.

Not only that, but it seems what we’re really trying to solve, in no small part, is the problem of trust. OpenChain is, of course, built around the cornerstone of creating trust in the open source software supply chain. Trust reduces friction and makes it possible for everyone involved to spend valuable time and resources on the things that are actually differentiating for one’s business.

But trust is also brought up when it comes to data – one needs to be sure that the data one is working with has integrity, that it has not been tampered with, that it does not infringe on anyone’s right to privacy, and that is of high quality. And the same applies to data spaces, which were quite heavily discussed in the AI track, regarding data provided by others.

Trust is also crucial for AI agents, which were also a topic presented in the AI track. There, I learned that 39% of US consumers have already used an AI agent to buy something online. This means that those 39% have provided an AI agent with a credit card. If we are to create an economy built heavily around agents, it’s quite clear that we absolutely need to emphasize the issue of trust, including trust in the underlying infrastructure.

And last but not least, trust would be a critical element in building a global system to manage the flow of vulnerability information, the topic of my talk on GVIP in the Cybersecurity track, where the conditions necessary to have trust in the system are explicitly formulated as a separate requirement.

The key takeaway from this three-day conference for me is the primary important we should all be placing on trust: trust in our infrastructure, trust in our software supply chain, and trust in our data supply chain. And if we are to have all of that, we would need to dedicate the necessary resources to create and implement the required standards and processes, and to build the necessary organizations, that make it possible to decide whom to trust and when.

The Cyber Resilience Act (CRA) is coming – what developers and open source users need to do now

By Featured

The session provided crucial guidance on preparing for CRA compliance presented by Thomas Liedtke. A key insight clarified the CRA’s interaction with open source. Pure open-source development – code published on platforms like GitHub without commercial activity or monetization – generally falls outside the CRA’s scope. However, at that moment when open-source software becomes part of a commercial product (e.g., an open-source library in commercial software, or components in IoT devices), the entire commercial product must be CRA compliant. Companies must evaluate if they provide “products with digital elements” and, if so, implement controls to secure them throughout their lifecycle.

The session detailed essential compliance activities like cybersecurity concepts, risk management, managing open source dependencies and software supply chain risks. To achieve the appropriate security level of your product you have to follow a risk-based approach, know the elements of the secure market placement and take care about strong access management and data protection, not mentioning the importance of the resilience of your systems. Among the others robust vulnerability management was also highlighted, with specific mention of Article 13 (manufacturers’ obligations) and Article 14 (reporting tasks). This session underscored that for any organization using open source in commercial offerings, understanding and proactively addressing the CRA’s requirements is absolutely essential for future market access. And do not forget about the industry specific regulations for medicine, automotive or aviation if you work in these areas.

Stronger Together: Networking for Cybersecurity Impact

By Featured

In today’s digital landscape, the threat surface is ever-expanding. We face an increasing tide of sophisticated attacks and data breaches, often perpetrated by well-organized adversaries who operate with the efficiency of a company. This reality highlights a critical truth: isolation is no longer an option for defense. The solution is clear: networking instead of silos – said by Christian Billmann. Creating communities and exchange ideas are getting more and more important that is the reason why Cybersecurity Region Stuttgart Meetup was created. Regional and local collaborations have a real impact on cybersecurity defense strategies. This initiative is dedicated to bringing people together, fostering connections, and sharing knowledge. Anyone interested can join their community, easily found on LinkedIn.

Another great initiative is the Automotive Security Research Group (ASRG) which was presented by Dirk Targoni. ASRG was born from the recognition that across the automotive industry, professionals facing similar problems related to cybersecurity. The increasing dependence on external data sources means shared challenges, and the logical response is to work together to solve them. ASRG currently boasts a dedicated network of over 100 volunteers working on different projects and researches.

In an era where attackers pool their resources and knowledge, it’s more critical than ever for defenders to do the same. We are not competitors; we are stronger together.


Using Apache Airflow to Automate Autonomous Driving Tests

By Featured

This presentation, “Using Apache Airflow to Automate Autonomous Driving Tests” by Bosch, details the significant challenges of testing software for autonomous vehicles and how Apache Airflow provides a robust solution.

The core problem lies in the sheer scale of testing required: to statistically prove that autonomous vehicles are safer than human drivers (e.g., 20% lower fatality rate with 95% confidence), an astronomical 14 billion kilometers of testing is needed. Physical testing alone would take 400 years with a fleet of 100 vehicles operating non-stop, making it impractical and statistically impossible for ensuring safety. Moreover, the “chaos of reality” (as illustrated by a chaotic street scene) demands testing across an immense number of complex scenarios. Standard CI/CD tools fall short here, as they are designed for short-lived code builds, not the massive test volumes, dynamic workflows, complex dependencies, and specialized hardware environments inherent to autonomous driving development.

Bosch, in collaboration with Cariad through the “Automated Driving Alliance,” adopted Apache Airflow as their orchestrator to manage thousands of parallel test executions. Airflow was chosen for its large community, Python-based workflow-as-code approach, enterprise-readiness, scalability, vendor/tech neutrality (Kubernetes, Spark/Hadoop, Docker), and Apache license, avoiding vendor lock-in. They even leverage Airflow for “Edge Worker” deployments to manage testing on remote sites with specialized hardware.

Key lessons learned include the importance of building on mature products rather than developing in-house solutions, leveraging the community for support, and prioritizing upstream contributions to minimize custom code. Bosch actively contributes to Airflow, helping shape its development in a direction that meets their critical safety needs.

Indeed, Bosch has been an extremely active contributor to the Apache Airflow project, making over 900 contributions, including new features, bug fixes, and improvements. They are deeply involved in the Airflow community through conferences, podcasts, and discussions, demonstrating a strong commitment to open-source collaboration and development. This extensive contribution highlights how they not only use Airflow but also actively help evolve it to meet the demanding requirements of autonomous driving test automation.


AI Systems Engineering: The New Discipline to Rescue AI from the “Valley of Death”

By Featured

AI is everywhere, yet true, reliable AI innovation often feels out of reach. With only 9% of organizations achieving AI maturity (Gartner 2024) and 95% of GenAI projects expected to fail (MIT 2025), it’s clear: AI needs a disciplined approach to move from hype to real-world impact.

Dr. Thomas Usländer from Fraunhofer IOSB highlighted a critical solution at OpenChain and Friends 2026: AI Systems Engineering.

Why You Need AI Systems Engineering

Simply put, AI only becomes an innovation when it’s reliably, securely, and efficiently applied. We’re currently in the “Trough of Disillusionment” on the Gartner Hype Cycle for AI – where initial excitement fades as projects hit roadblocks. AI Systems Engineering is our map out of this trough.

It’s about treating AI not as magic, but as complex systems that need proper engineering.

What Is It? (The Core Idea)

AI Systems Engineering is a new discipline focused on:

  1. Methodology: Structured ways to build and deploy AI. Think of PAISE® (Process Model for AI Systems Engineering) – it even treats data as “sub-systems” with their own development cycles.
  2. Data Management (Data Spaces): AI needs data! Open, secure data-sharing platforms like Catena-X are crucial for industrial AI to scale and work together.
  3. Responsible AI: With regulations like the European AI Act, building AI responsibly (considering roles, risks, and ethics) isn’t optional – it’s integrated into the engineering process.
  4. System-Wide View: AI isn’t just an algorithm; it’s part of a larger system. This discipline ensures AI integrates smoothly and safely into broader operations.

AI Systems Engineering + Data Spaces: The Perfect Pair

These two concepts are inseparable. AI Systems Engineering gives you the “how-to” (the engineering process), while Data Spaces provide the “what-to-use” (the secure, shared data). Together, they enable the efficient development, deployment, and operation of AI systems, especially for industrial uses.

The Bottom Line

AI is powerful, but its true value is unlocked through discipline. AI Systems Engineering is crucial for making AI reliable, compliant, and genuinely innovative. Without it, many AI projects risk getting stuck in the “Valley of Death.” It’s the engineering foundation AI needs to thrive.